To scrape Reddit posts and comments, first choose an access method that fits your use case and Reddit’s current rules. Developers can use the official Reddit API through OAuth and a wrapper such as PRAW. Non-coders can use a visual workflow or a preset Octoparse template to turn permitted public threads into structured rows for Excel, CSV, or JSON.
The difficult part is no longer finding a script. It is choosing a route that returns the fields you need without assuming that public visibility equals unlimited permission. This guide compares the practical options, then shows how to collect post and comment data without building a crawler from scratch.
This guide explains how to scrape Reddit data—including posts, comments, replies, engagement metrics, and available media URLs—then export it for analysis.
Reddit data you can collect
A Reddit scraper converts information from posts and discussion threads into a structured dataset. Depending on the page, method, permissions, and content availability, the dataset may include post text, engagement metrics, comments, replies, media links, and community details.
| Data group | Typical fields | Useful for |
|---|---|---|
| Post | Subreddit, title, body text, author, post URL, publish time | Topic discovery, content research, issue tracking |
| Engagement | Score or upvotes, comment count, reply activity | Prioritizing discussions and measuring interest |
| Comments | Comment author, text, time, score, permalink | Voice-of-customer research and sentiment analysis |
| Replies | Reply author, reply text, time, score, parent context | Understanding how discussions develop |
| Media | Post image URL or comment image URL when available | Media monitoring and dataset enrichment |
Availability is not guaranteed. Deleted comments, removed posts, restricted communities, collapsed branches, and content behind authentication may not appear. Treat every exported field as a snapshot, not a permanent record of everything that once existed on the page.
Choose a Reddit scraping method
The best way to scrape Reddit depends on volume, technical skill, output format, and authorization. Manual copying is enough for a handful of posts. The official API gives developers structured access. A no-code template is faster when the goal is a spreadsheet rather than an application.
| Method | Best fit | Setup | Main limitation |
|---|---|---|---|
| Manual collection | A few posts or quotes | Open pages and copy permitted information | Slow, inconsistent, and difficult to repeat |
| Reddit developer platform | Developers building an approved Reddit integration | Follow Reddit’s current Devvit or approved Data API route | Terms, permissions, limits, and use restrictions apply |
| Python with PRAW | Developers with approved external OAuth access | Install PRAW and configure the credentials Reddit permits | PRAW does not grant API access or remove Reddit’s requirements |
| Octoparse preset template | Non-coders collecting known post threads | Enter supported Reddit post URLs and run the template | The current template requires old.reddit.com post URLs |
| Custom visual workflow | Pages or fields not covered by a preset template | Build and maintain extraction steps in the desktop app | More setup and maintenance than a preset template |
Which Reddit integration should you use?
A Reddit integration connects permitted Reddit data access to an application, automation, or analysis workflow. Choose the integration according to where the workflow runs and how the result must be delivered.
- Reddit Devvit: Best for approved apps that run within Reddit communities and use platform-managed authentication.
- PRAW: Best for Python workflows using external OAuth credentials and the access Reddit has approved.
- Octoparse Cloud or MCP: Best for no-code or AI-assisted collection when a supported template can turn permitted public post URLs into structured exports.
Use the official API or PRAW when your product needs programmatic access and your use case meets Reddit’s requirements. Use the preset template when you already have post URLs and need posts, comments, and replies as rows. Use a custom workflow only when the preset template does not cover the page type or fields you need.
Reddit access and compliance in 2026
Public visibility is not blanket permission for automated collection. Reddit’s current User Agreement restricts automated data collection except where the terms or a separate agreement permit it. The Reddit Data API Terms govern Data API access and require compliance with Reddit’s rules, approved use, applicable limits, and content-rights obligations.
Reddit also states that commercial use, research beyond rate limits, or another use not expressly permitted may require a separate agreement. User content remains owned by its creators, and API access does not automatically grant the right to republish, resell, retain, or use that content for AI training.
Before collecting data, define the purpose and the minimum fields required. Avoid private or restricted content. Do not bypass login walls or technical controls. Minimize personal data, respect deletion and removal requests, and consult qualified counsel for commercial, regulated, or high-risk projects. Octoparse’s web scraping legal guide provides broader context, but it is not legal advice.
Scrape Reddit posts and comments with Octoparse
Octoparse is a visual web data platform for building extraction workflows without writing a crawler from scratch. For a local desktop workflow, start with the https://www.octoparse.com/template/reddit-scraper.
For cloud automation through Octoparse MCP, use the https://www.octoparse.com/template/reddit-post-comments-scraper. This is a separate Cloud template. Its required MCP input field is old_Reddit_Post_URLs, passed as an array of old.reddit.com post URLs. As verified on August 21, 2026, the Standard plan lists a price of $0.1 per 1,000 exported rows.
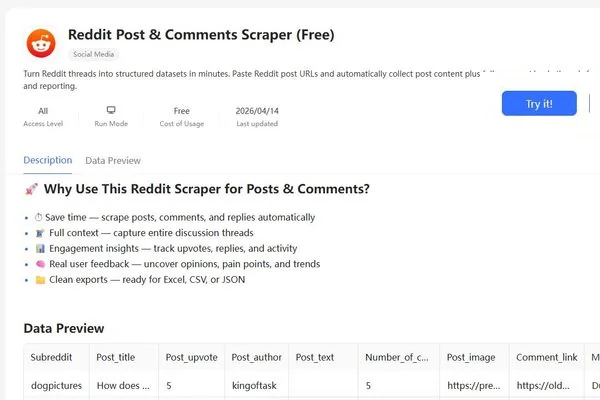
As verified on August 21, 2026, the public template page lists the template as free, last updated April 14, 2026, and designed for up to 1,000 Reddit post URLs per run. Access levels and supported run modes can change, so check the live page before planning a production workflow.
Step 1. Prepare permitted Reddit post URLs
The preset template works from individual post URLs, not a subreddit name or a general keyword. Collect the threads relevant to your research question. For example, a product team might select threads discussing one feature, while a content team might collect discussions around one recurring problem.
The current template requires the old.reddit.com format. Convert a standard post URL by changing only the domain:
Do not add URLs for private, quarantined, age-restricted, or otherwise inaccessible content. If you need to discover posts first, use Reddit search or review the relevant community manually, then keep only the permitted post URLs that match the project scope.
Step 2. Open the preset Reddit template
Open the Reddit Post & Comments Scraper from the live template page. You can also search the Octoparse template library for Reddit workflows that collect keyword results, trending posts, or subreddit listings.
Select Try it! to open the input screen. The template page describes a single required input: Reddit post URLs, one per line, with a published limit of up to 1,000 URLs.
Step 3. Enter a small test batch
Start with a small batch of representative threads. Include one short discussion and one thread with replies so you can inspect how the output handles empty fields and nested content. A small validation run helps you catch URL-format or field-coverage problems before processing a larger list.
Paste one URL per line. Check that every domain is old.reddit.com and that each URL opens the intended post. Remove duplicates before starting the task.
For an MCP run, pass the same URLs as a JSON array:
Step 4. Run the template and inspect the output
Start the supported run mode shown in your account. The public template preview lists fields for subreddit, post title, post text, post author, post upvotes, comment count, post image, comment link, main-comment details, reply details, and last-level reply details.
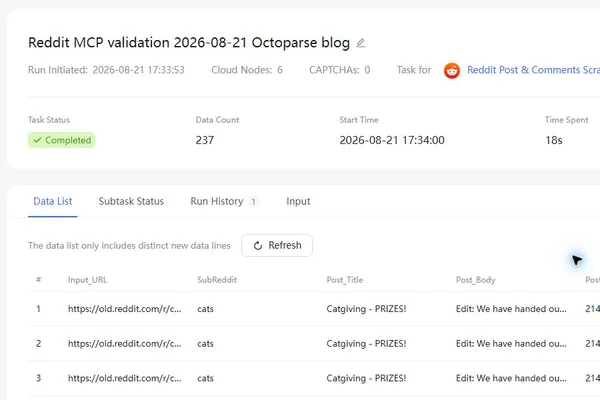
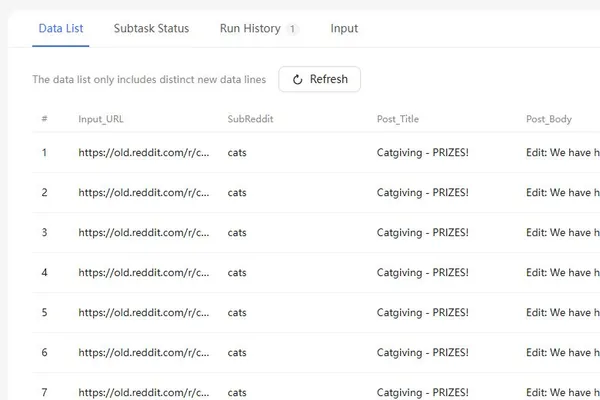
In an Octoparse MCP validation run on August 21, 2026, one public Reddit post URL completed successfully and returned 237 rows in 18 seconds. A five-row export sample retained the source URL, subreddit, post title, post author, post upvotes, comment count, comment text, commenter, comment time, comment URL, and comment ID. The reply fields were empty in that first sample, so test a thread with known nested replies before relying on reply-level analysis.
Step 5. Export Reddit data to Excel, CSV, or JSON
Review several rows before export. Make sure comments remain associated with the correct post and that reply fields are not mistaken for top-level comments. Then export the dataset in the format that matches the next step:
- Excel: Best for manual review, filtering, and sharing with non-technical teams.
- CSV: Best for spreadsheets, BI tools, databases, and Python analysis.
- JSON: Best for preserving field names and sending the data into an application.
If the preset template does not cover the page or field you need, download the Octoparse desktop app and build a custom visual workflow. A custom task offers more control, but it also requires ongoing maintenance when Reddit changes its page structure.
Scrape Reddit with Python using PRAW
PRAW is a Python wrapper for the Reddit API. It makes Reddit objects easier to work with, but it does not bypass Reddit’s authentication, approval, rate-limit, or use requirements.
Follow the official PRAW Quick Start for wrapper setup, and check Reddit’s current developer-platform API overview before choosing an integration route. Reddit’s 2026 documentation distinguishes Devvit from traditional API usage: Devvit handles authentication after an app enables the Reddit permission, whereas PRAW expects external OAuth credentials. A basic PRAW setup begins with the library:
Use the following configuration only when Reddit has approved external OAuth access for the intended use and issued the required credentials. Store the client ID, client secret, and user agent outside the source file. A read-only client can then access only the resources, scopes, and limits Reddit grants to that integration.
This example only shows credential configuration. It is not proof that a particular endpoint, account, or commercial use has been approved. Check the current API documentation and your agreement with Reddit before adding collection logic.
Turn the Reddit export into usable analysis
A large Reddit export is not automatically useful. Keep the post URL, comment permalink, timestamp, and subreddit with every row so an analyst can trace the source and understand the conversation context.
Market research: Group posts and comments by problem, product, or competitor. Review repeated language before assigning sentiment labels.
Content research: Identify recurring questions and misunderstandings. Do not republish user comments as your own content. Quote only when the intended use and rights permit it.
Product feedback: Separate feature requests, defects, workarounds, and praise. A highly upvoted comment can indicate community agreement, but it is not a representative customer survey.
Conversation analysis: Preserve parent and reply context when possible. Flattening every comment into an isolated sentence can distort what the author was responding to.
Fix common Reddit scraping problems
| Problem | Likely cause | Practical response |
|---|---|---|
| The template rejects a URL | The domain is not old.reddit.com or the URL is not an individual post | Convert the domain and open the URL manually before retrying |
| Some comments are missing | Deleted content, removed content, collapsed branches, restrictions, or incomplete loading | Document the limitation and avoid claiming complete coverage |
| Rows contain many blank reply fields | Not every top-level comment has a reply | Filter by comment level during analysis instead of deleting the parent row |
| The layout or fields change | Reddit or the template was updated | Check the live template page and revalidate a small batch |
| The API returns an authorization error | OAuth, app approval, scope, or policy requirements are not satisfied | Review Reddit’s current API rules rather than trying to bypass the error |
FAQs about scraping Reddit
Can I scrape Reddit without coding?
Yes, a no-code tool can turn supported Reddit pages into structured rows without requiring Python. The current Octoparse Reddit Post & Comments Scraper accepts supported post URLs and lists post, comment, and reply fields. You still need a permitted use case and must follow Reddit’s current terms and access rules.
Can I scrape an entire subreddit with the comments?
The preset Post & Comments template starts from individual post URLs, not a subreddit homepage. A practical workflow is to identify permitted post URLs first, then feed those URLs into the comment template. Validate the process on a small batch because deleted, restricted, or deeply nested content may be incomplete.
Is the Reddit API free?
Do not assume every Reddit API use is free. Reddit’s Data API Terms state that Reddit may charge fees and that commercial use, research above rate limits, or another use not expressly permitted can require a separate agreement. Review the current terms and obtain the access appropriate for your project.
What is the difference between a Reddit scraper API and PRAW?
PRAW is a Python wrapper around Reddit’s official API, so Reddit’s credentials, permissions, and limits still apply. “Reddit scraper API” is a broader commercial phrase used for services that return Reddit data through their own endpoints. Verify each provider’s authorization, fields, pricing, retention rules, and compliance claims before use.
Why are deleted Reddit comments missing?
A scraper cannot reliably recover content that is no longer available through the permitted source. Deleted or moderator-removed comments may be absent, while collapsed or deeply nested comments may require additional loading. Record the collection time and limitations instead of describing the export as a complete historical archive.
Do you need a Reddit scraper or downloader?
Use a Reddit scraper when you need a structured dataset with post text, comments, authors, scores, timestamps, and available media URLs. Use a Reddit downloader when you only want to save a permitted video, audio track, GIF, image, or gallery for offline use.
For a quick browser-based option, try RedVid.io. Paste the Reddit post link, choose an available format or quality, and save the file. RedVid says no registration or software installation is required. Use it only for content you own or are authorized to download. Octoparse serves a different need: exporting Reddit records and media URLs for analysis.
Build a repeatable Reddit data workflow
The reliable way to scrape Reddit in 2026 is to match the method to the task. Use the official API or PRAW for an approved developer integration. Use the Octoparse preset template when you have supported post URLs and need a no-code spreadsheet. Use a custom workflow only when the preset route does not cover the required page or field.
Start small, keep source context, and document missing content. Most importantly, treat access, rights, and data minimization as part of the workflow rather than an afterthought.